LLM-as-a-Judge: How Reliable Are LLM Judges, and How to Evaluate an LLM App or Agent
Published · 22 min read
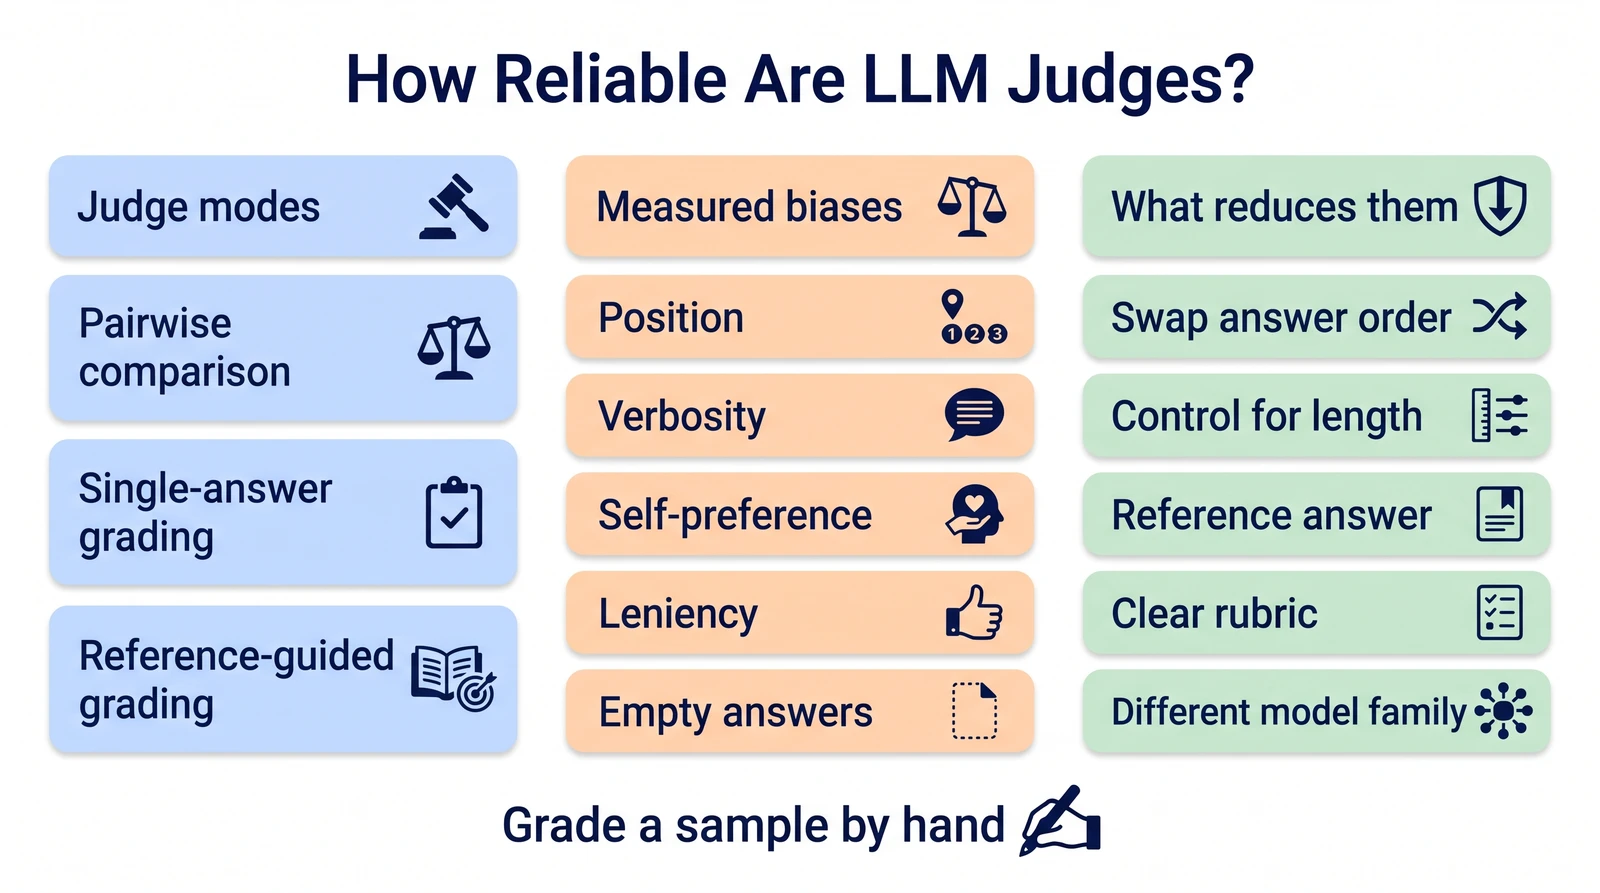
LLM as a judge means you use one language model to grade the output of another. A strong judge can agree with people about as often as people agree with each other, and it also fails in ways that are now well measured. In the MT-Bench study, GPT-4 agreed with human experts on 85% of non-tie votes, while two experts agreed with each other on 81%. In the same study, GPT-4 kept its verdict on only 65% of answer pairs when the order of the two answers was swapped.
This article collects what peer-reviewed research and the OpenAI, Anthropic and Google evaluation guides say about how reliable LLM judges are, which biases have been measured, and what reduces them. It then covers how to evaluate an LLM app, a RAG pipeline and an agent.